Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated
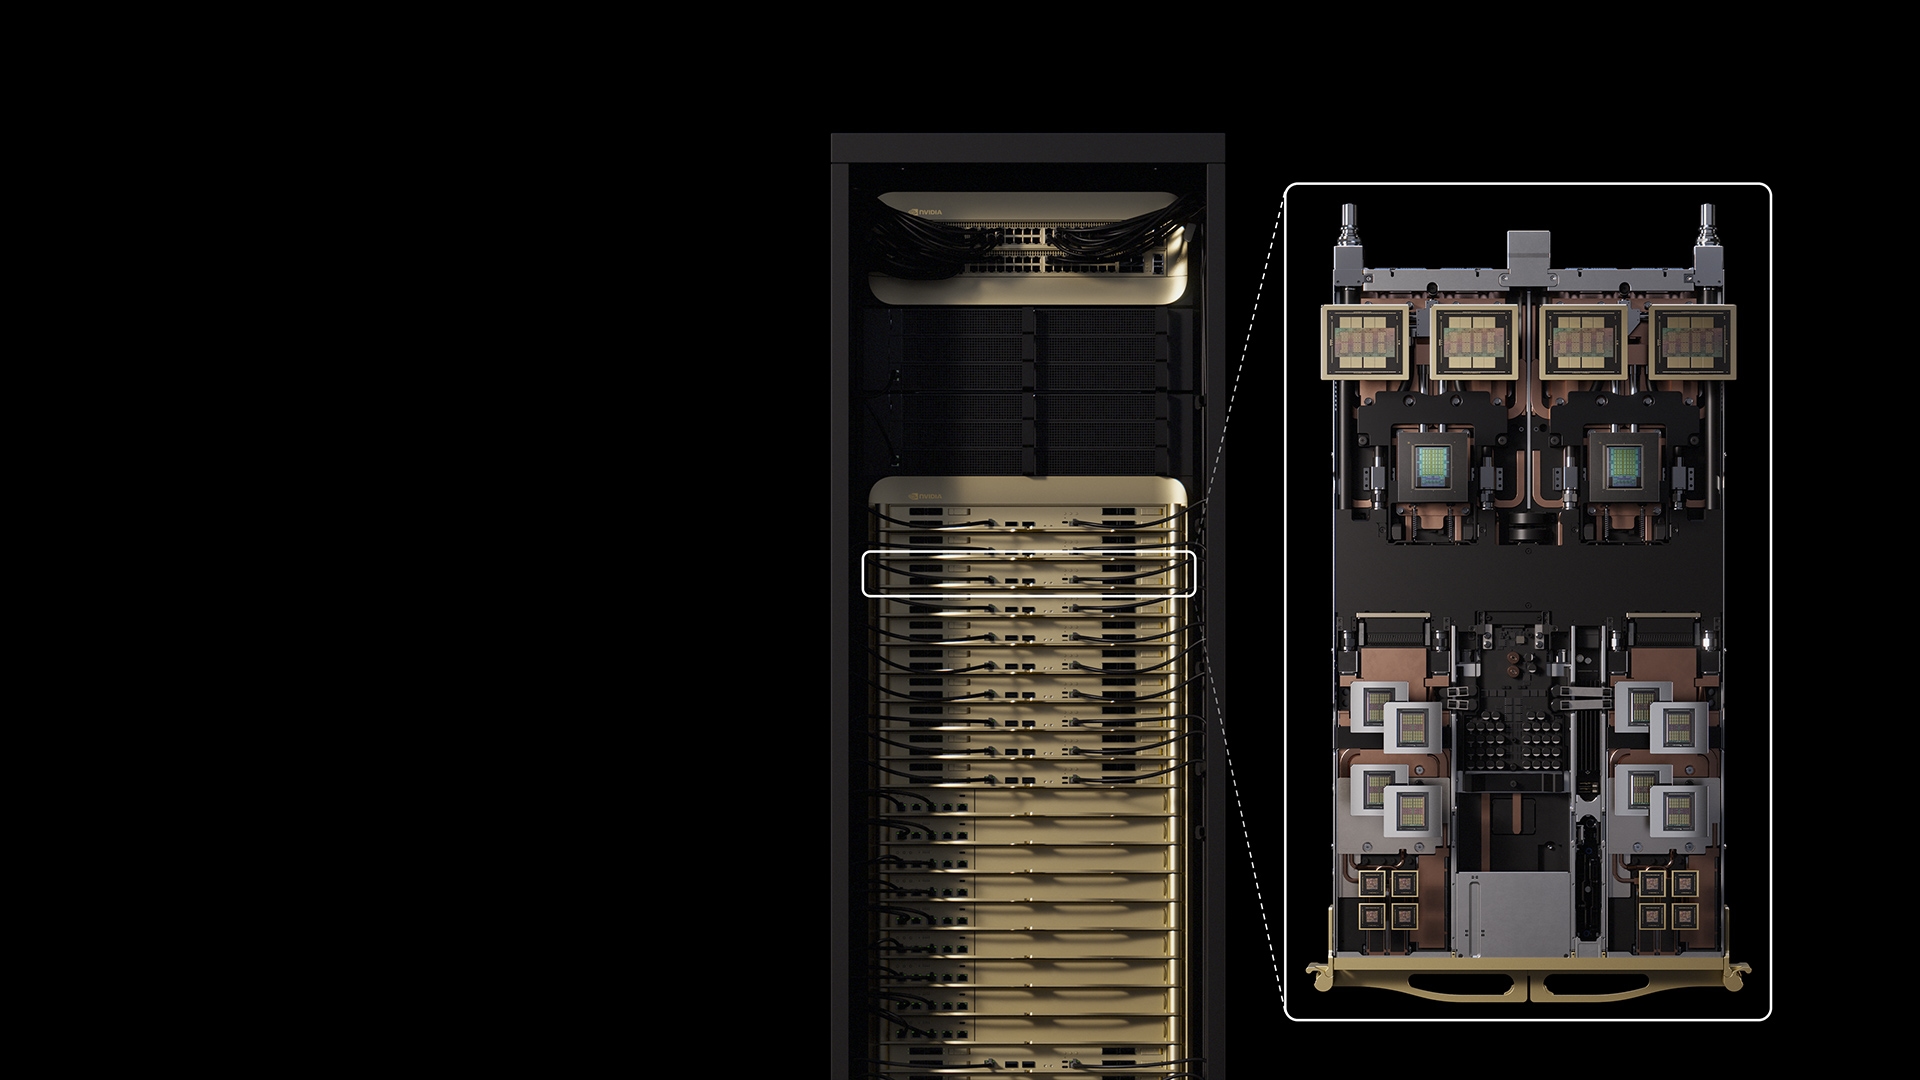
Nvidia is moving its Groq 3 LPX inference chip into full production and reports 3,400 tokens per second on Gemma 4 31B, four times faster than Cerebras. But the numbers don't tell the whole story. Nvidia needs at least 64 accelerators to get there, while Cerebras needs only one or two, according to The Register. How well the architecture scales with large MoE models remains an open question.
The article Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated appeared first on The Decoder.
Rating
Innovation
Pricing
Technology
Usability
We have discovered similar tools to what you are looking for. Check out our suggestions for similar AI tools.
Inference is splitting in two — Nvidia’s $20B Groq bet explains its nex
<p>Nvidia’s $20 billion strategic licensing deal with Groq represents one of the first clear moves in a four-front fight over the future AI stack. 2026 is when that fight becomes obvious to en [...]
Nvidia, Groq and the limestone race to real-time AI: Why enterprises win or
<p>From miles away across the desert, the Great Pyramid looks like a perfect, smooth geometry — a sleek triangle pointing to the stars. Stand at the base, however, and the illusion of smoot [...]